A memory layer for language models.
Less rereading. More usable memory.
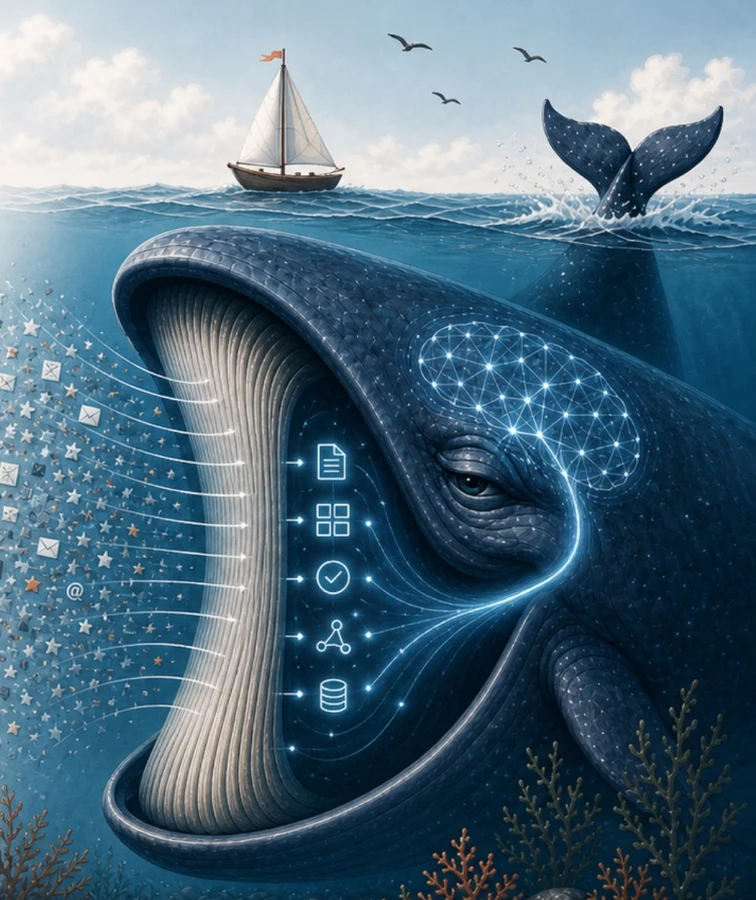
Core
Hetula turns text into memory.
Memory is built from meanings, connections, conditions and exceptions.
Intuition
Human memory is not a chat log.
We usually remember meanings, connections and context. Word for word recall is often secondary. Hetula brings the same basic idea to an AI memory layer.
An analogy, not a copy of the brain.
The problem
Text is not memory.
Problem 1
Everything is reread on every turn.
A larger window does not remove the problem. Compute, latency and noise grow with it.
Compute grows. Latency grows. The useful part gets buried.
Illustrative. Each turn re-sends everything said so far.
Problem 2
When everything stays as text, nothing really expires.
Old information, new information and wrong information can all end up in the same pile.
Same weight, same place, no expiry.
Where it sits
Hetula sits in front of the model.
The same layer works with different language models. The model stays the same. Memory lives in a separate layer.
How it works
One memory, four moments.
Follow one sentence about Pekka from text to memory, through a question, an update and the moment the source is set aside.
Memory · Pekka
source text
Pekka likes his coffee strong, but only in the morning, not in the evening.
source separated
new information
Pekka has switched to milder coffee.
question
What coffee does Pekka want in the morning?
basis: same person, same subject, right situation
memory remains usable
Step 1. Storage
Text becomes memory when it is stored.
Hetula keeps what needs to be remembered.
Benefit
Light.More memory fits into the same context.
The model gets only what the situation needs. Less rereading, less compute.
Step 2. Retrieval
A question activates the right part of memory.
Retrieval focuses on the memories that matter in the situation.
Benefit
Explainable.The answer can show what it was based on.
Memory is not a guess. The reason for a match can be shown to a person or a system.
Step 3. Update
When information changes, memory changes with it.
New information can replace old information in a controlled way.
Benefit
Updatable.The assistant uses what applies now.
Outdated information does not disappear mysteriously. It steps aside in a controlled way.
Step 4. Source
The original text does not have to be read on every retrieval.
The source can be handled separately from normal memory retrieval. The memory can remain usable even when the original text is not read each time.
Benefit
Cleanable.Memory has to be manageable afterwards.
In company use, you need to know what is kept, what is updated and what is removed.
The hard part
Good memory needs selection.
- The memory layer has to choose what is worth keeping.
- Retrieval has to find the right memory at the right time.
- Cleanup has to remove old information without breaking usefulness.
High level view
What Hetula does to memory
Text becomes memory. A question finds the right parts. Old information can step aside. The answer can show its basis.
Technical details, algorithms and benchmarking with your own data can be discussed separately.
Hetula in practice
What this means in practice.
Less rereading.
Less unnecessary context and compute.
Updatable, removable and explainable.
Built in front of existing and future models.
Tests
Less unnecessary context. More manageable memory.
These results come from a use case that suits a memory layer. Hetula does not fit every task. A benchmark on your own data shows early whether it fits yours.
- Explainability: the answer can show its basis.
- Removability: the source can be handled separately.
- Updating: old information can step aside.
- Targeted memory: only what is needed activates.
Measured in tests, not in production. Your own data should be benchmarked separately.
Next step
What I would test with you.
Same task. Same model. Same data.
The first result is a fit check: does memory beat rereading in your task at all? If it does not, the benchmark says so, and we stop there.
Baseline
long context or source snippets
Hetula
memory layer in front of the model
measured
tokenslatencycostrecallanswer basisupdate handlingCore
Hetula turns model memory into more than a pile of text. Memory that can be used at the right moment and cleaned up afterwards.
Contact
If this touches a memory problem you already have, start with a benchmark against your own data.
Same task. Same model. Same data.
Jussi Kallioniemi · LinkedIn